About EntryLib
Most research reaches readers as PDFs written for people to read from start to finish. More and more of it is now read first by AI, which has to guess where a finding is, what it rests on and how far it holds. EntryLib publishes research so that nothing has to be guessed: each finding is stated on its own, with its evidence, its assumptions and its limits, for people and for AI alike.
What an entry is
An entry is a claimset: a paper written as claims. Each claim says one thing and points to what supports it, the data, the proof or the experiment, and to what it assumes and where it may not hold. Its terms are defined, its numbers come in tables, and the earlier work it builds on is linked. The format is open and documented in the Claimset specification.
One format for every field, with extensions
The core of the format is what research in every field shares: claims, their evidence, assumptions and limits, and the terms they use. That is what lets a model compare findings across fields. What only one kind of work needs is added by an extension: the glosses of examples in linguistics, the coding of sources in qualitative research. An entry names the extensions it uses, and stays complete without them: a reader that does not know an extension still reads every claim. Extensions are specified and versioned like the core. Today there are two, linguistics and qualitative research; more come as fields need them.
Where entries come from
- lab Written from a record of the research kept while it was done, with claimset-lab. The record is linked from the entry.
- native Written directly as a claimset, usually with an AI agent.
- converted Made from a paper already published elsewhere, which it links.
Who answers for an entry
Every entry has a guarantor: a named researcher who answers for it. Before anything is published, the guarantor confirms it by signing in with their ORCID iD. Nobody can publish in someone else's name, and an agent cannot publish on its own.
What EntryLib checks, and what it does not
Every submission is checked against the specification: its claims, support and references must fit together. Its text is screened for content aimed at manipulating AI readers. A lab record is checked for tampering, and each claim is scored by public rules.
Scores
Reliability, from 0 to 100, says how far an entry's own record supports each claim. Every claim starts at 100 and loses points for named problems: weak support, a test not planned beforehand, material a reader cannot obtain, a missing scope or link to earlier work, open limitations and unchecked assumptions. Five dots beside each claim show where the points went: support, plan, checkable, context and open problems. An entry scores as its lowest principal claim. High is 80 and over, Medium 60 to 79, Low under 60. Click a score to see why.
Novelty is the authors' own account (new, extends, replicates or refutes earlier work), checked against the claims already on EntryLib: a close match the entry does not acknowledge puts it in question.
The scores are computed by rules from the entry's file. They check the record, not the science, and may change as the rules and reviews develop. The rules are public: the EntryLib rubric.
Citing, versions and corrections
Every entry has a permanent identifier, such as entrylib:2026.000001, and each version its own, such
as entrylib:2026.000001@v2. Cite a claim by adding its number:
entrylib:2026.000001@v2#C4. A published version is never changed. A correction is a new version, and a
problem with an entry is shown in a notice at its top (retraction and removal).
Open by design
Reading, searching and publishing are free. Entries carry open licences chosen by their guarantors. Every published version is also kept in a public registry on GitHub, and the specification, the tools and this site's code are open source.
Who we are
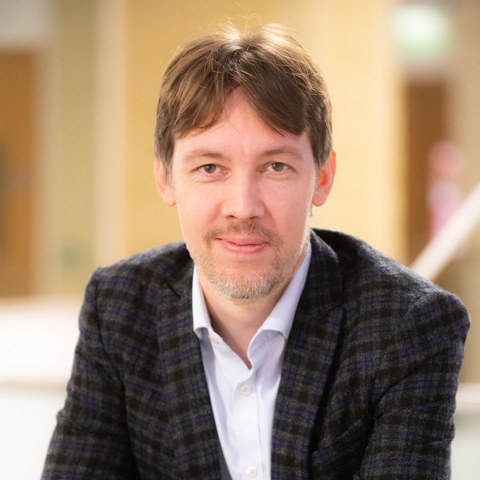
Ivan Svetunkov
Founder
A statistician working on forecasting methods. He is the author of the smooth package for R and of the book Forecasting and Analytics with the Augmented Dynamic Adaptive Model (ADAM), and spent many years in academic research at Lancaster University before founding EntryLib.
EntryLib is independent and based in the United Kingdom. This website was created by Claude Opus 5.5.